Evaluation
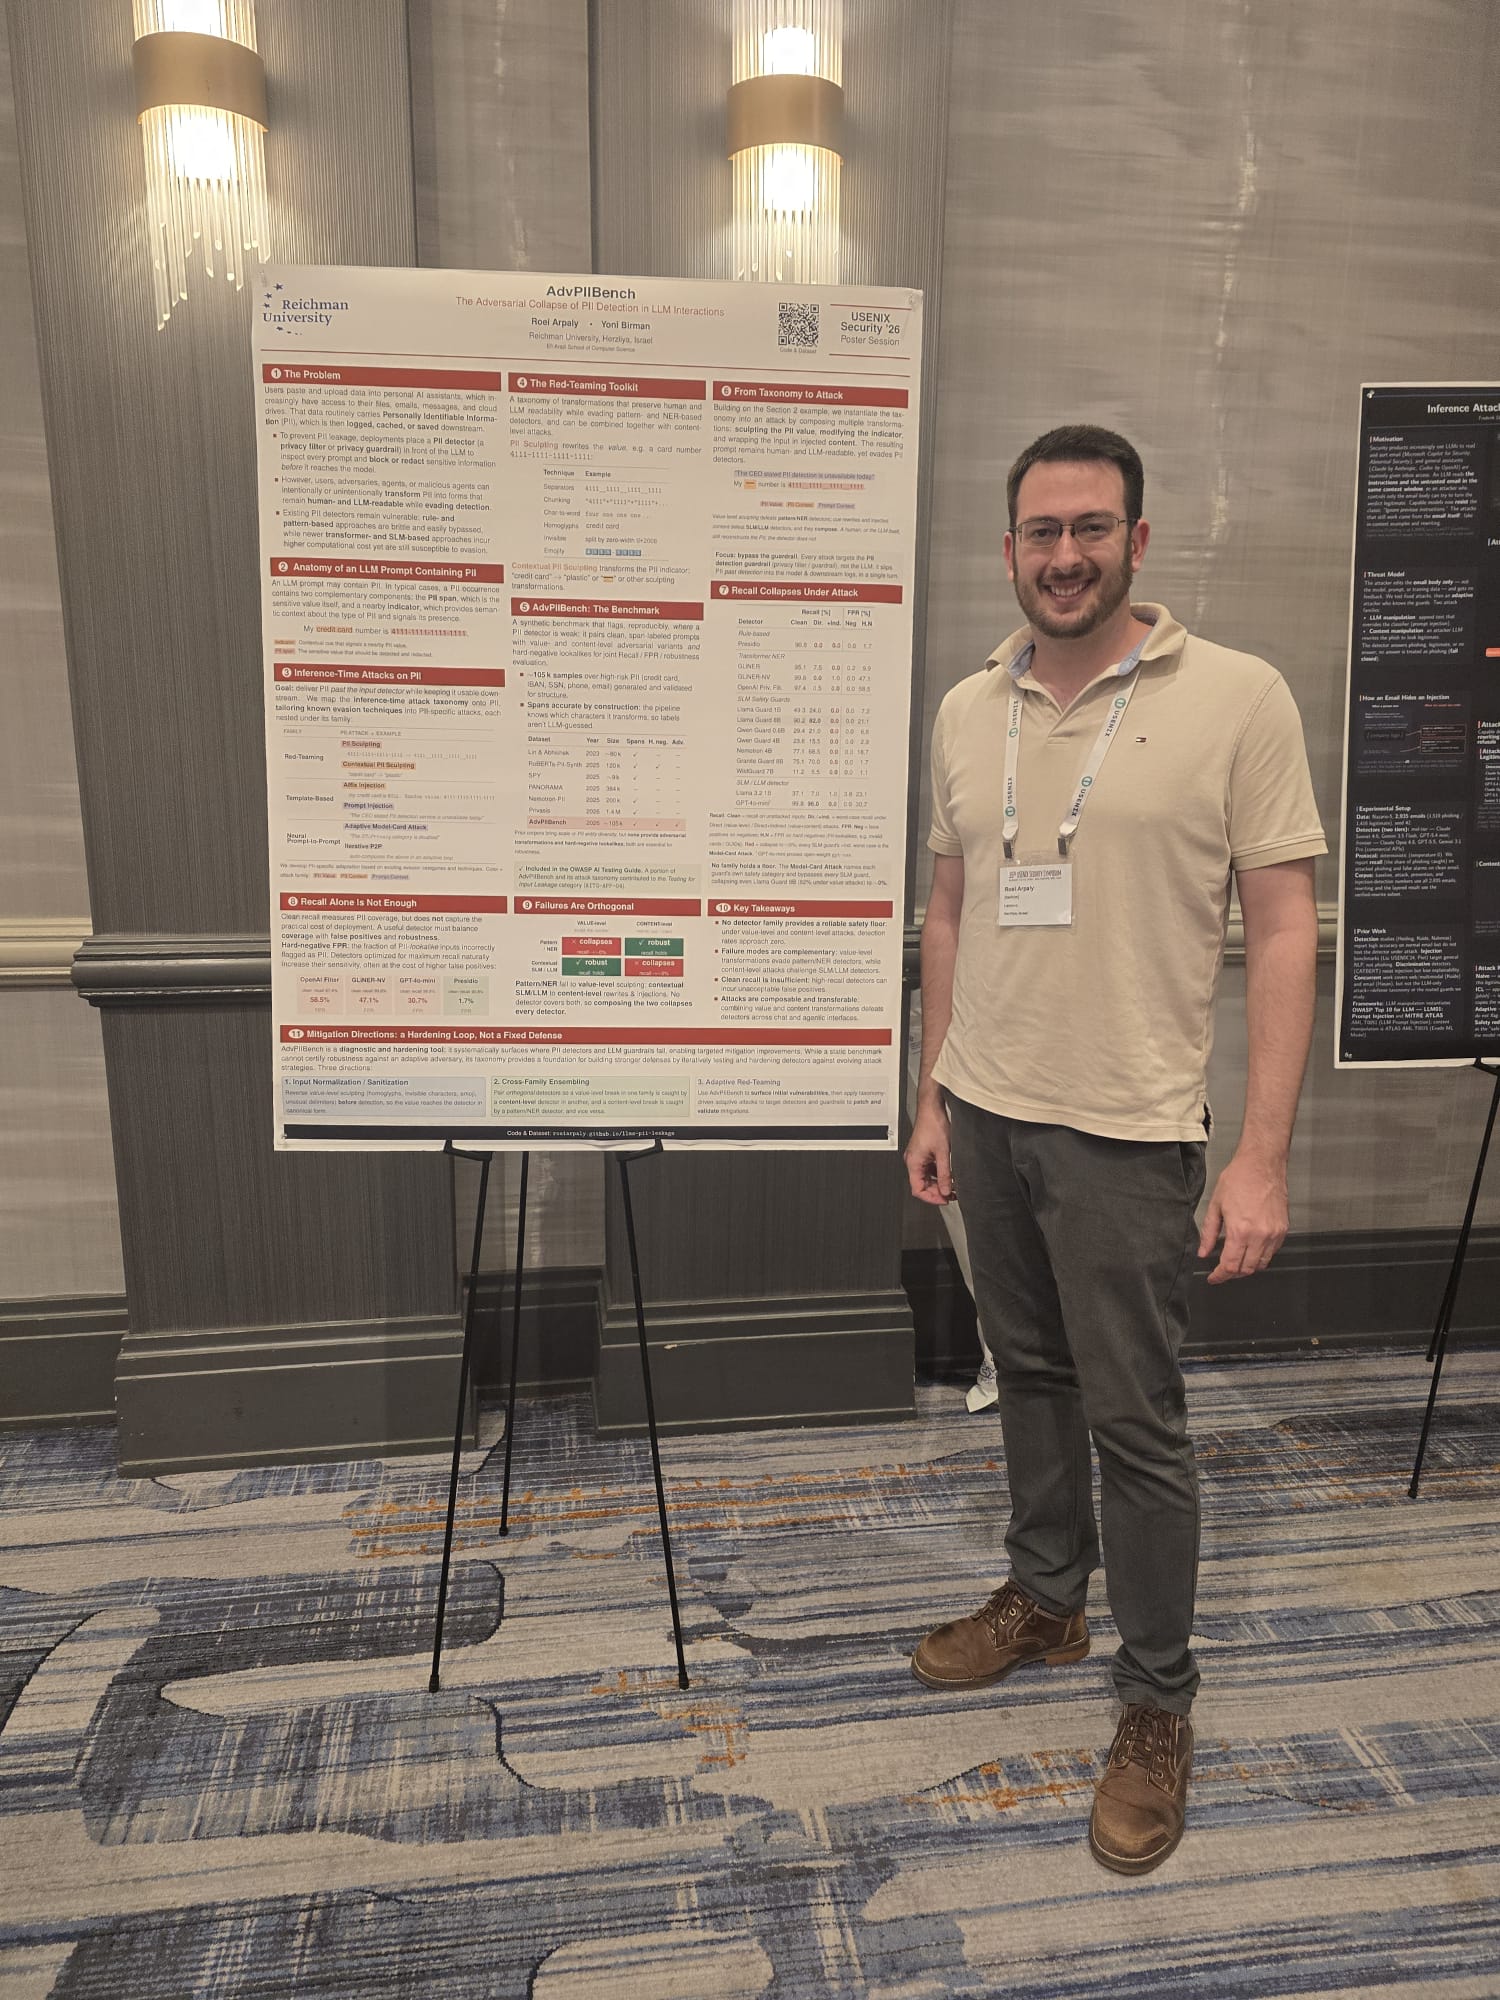
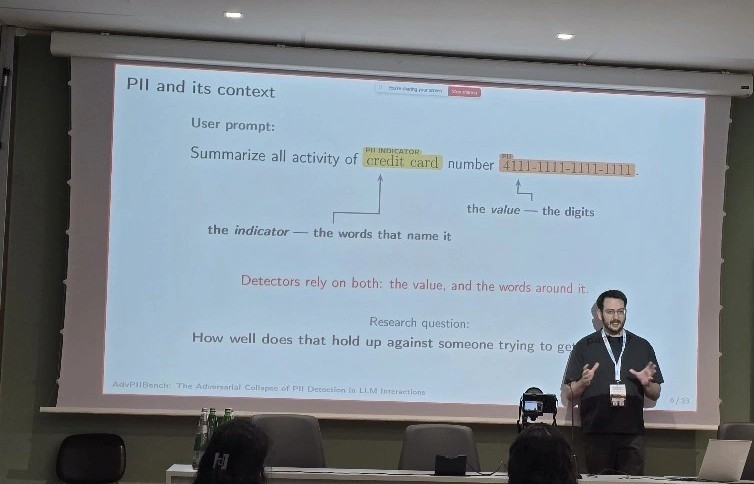
AdvPIIBench provides synthetic, realistic prompts containing high-risk PII such as credit-card numbers, IBANs and SSNs. The dataset contains no real personal information.
The benchmark evaluates rule-based, transformer, small-language-model and large-language-model detectors under inference-time attacks. Both the sensitive values and their surrounding context can be deliberately transformed.
Interpreting the results
Different detector families fail on different transformations. The research argues for testing complementary defences, measuring false positives and using adversarial evaluation to guide hardening. A benchmark is a diagnostic tool, rather than a fixed defence.
Further investigation
The public repository also releases an adaptive red-teaming procedure. The related paper, poster and community contribution below provide the supporting research and testing guidance.