Completed research · 2026
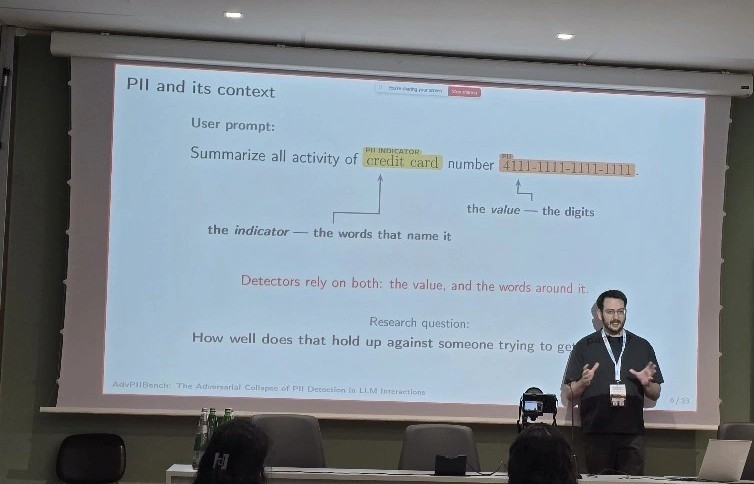
AdvPIIBench
An open benchmark for testing PII detection when sensitive values and their context are deliberately transformed.
AI Safeguards and runtime defenses
How can safeguards recognise risky inputs, outputs and actions while preserving useful AI behaviour?
AI systems encounter changing inputs and can act through connected tools. We explore safeguards around those interactions, including how several controls work together, how decisions are monitored and when a system should pause for human review.
Study safeguards for model inputs, generated outputs and tool actions.
Examine layered controls and the gaps between their individual decisions.
Investigate monitoring, escalation and safe handling of uncertain decisions.
Evaluate protection alongside false alarms, response time and useful task completion.
Completed research · 2026
An open benchmark for testing PII detection when sensitive values and their context are deliberately transformed.
USENIX Security 2026 · Poster session
SECAI 2026 @ ESORICS · Paper and oral presentation
Explore student research, internships and collaboration with the lab.